

moabb.datasets.Daly2020#
- class moabb.datasets.Daly2020(subjects=None, sessions=None, *, return_all_modalities=False)[source]#
Bases:
OpenNeuroMirrorMixin,BaseBIDSDataset[source]Dataset Snapshot
Daly2020
Imagery, 2 classes (right_hand vs relax)
Imagery Code: Daly2020 18 subjects 1 session 19 ch 1000 Hz 2 classes 20.0 s trialsClass Labels: right_hand, relax
Citation & Impact
- Paper DOI10.18112/openneuro.ds002720.v1.0.1
- CitationsLoading…
- Public APICrossref | OpenAlex
Stimulus Protocol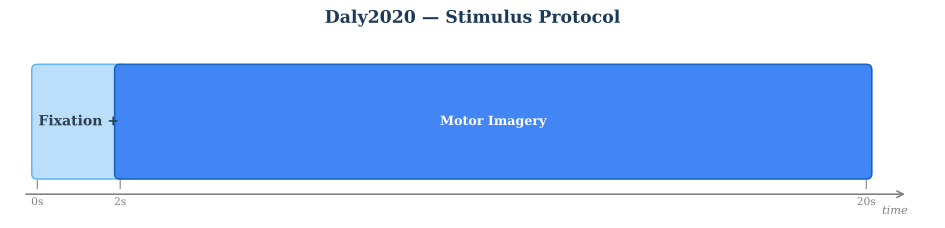
20s task window per trial · 2-class imagery paradigm · 8 runs/session across 1 sessions
HED Event TagsHED tagsSource: MOABB BIDS HED annotation mapping.
right_handSensory-eventAgent-actionrelaxSensory-eventLabelHED tree view
Tree · right_hand
├─ Sensory-event │ ├─ Experimental-stimulus │ └─ Visual-presentation └─ Agent-action └─ Imagine ├─ Move └─ Right └─ HandTree · relax
├─ Sensory-event └─ Label
Channel SummaryTotal channels19EEG19Montagestandard_1020Sampling1000 HzReferenceFCzNotch / line50 HzThis diagram is automatically generated from MOABB metadata. Please consult the original publication to confirm the experimental protocol details.
Tempo-based BCMI motor imagery dataset from Daly et al. 2018 [1].
Recorded at the University of Reading during development of a tempo-based brain-computer music interface (BCMI-MIdAS). 18 healthy participants raised the music tempo by imagining squeezing a ball in their right hand (right_hand, event 1, “Lower alpha”) and lowered it by relaxing (relax, event 2, “Raise alpha”). Each subject has 9 runs of alternating 20 s trials; the calibration run 1 (empty events file) and the targetless runs sub-05/run2, sub-15/run3 and sub-17/runs2-3 are skipped, and the rest are exposed as runs
"0","1", … of session"0".Note
The README states 19 participants and CC-BY-4.0, but the release contains 18 subjects and
dataset_description.jsonsays CC0; this loader follows the release. The summary table reports the designed 72 trials per class; retained counts can be lower.References
[1]Daly, I., Nicolaou, N., Williams, D., Hwang, F., Kirke, A., Miranda, E., & Nasuto, S. J. (2018). A dataset recorded during development of a tempo-based brain-computer music interface. OpenNeuro ds002720. https://doi.org/10.18112/openneuro.ds002720.v1.0.1
from moabb.datasets import Daly2020

dataset = Daly2020()
data = dataset.get_data(subjects=[1])
print(data[1])
Dataset summary
#Subj
18
#Chan
19
#Classes
2
#Trials / class
72
Trials length
20 s
Freq
1000 Hz
#Sessions
1
#Runs
8
Total_trials
2592
Participants
Population: healthy
Equipment
Montage: standard_1020
Reference: FCz
Data Access
DOI: 10.18112/openneuro.ds002720.v1.0.1
Data URL: https://openneuro.org/datasets/ds002720
Experimental Protocol
Paradigm: imagery
Feedback: continuous
Stimulus: auditory music tempo
- property all_subjects#
Full list of subjects available in this dataset (unfiltered).
- convert_to_bids(path=None, subjects=None, overwrite=False, format='EDF', verbose=None, generate_figures=False)[source]#
Convert the dataset to BIDS format.
Saves the raw EEG data in a BIDS-compliant directory structure. Unlike the caching mechanism (see
CacheConfig), the files produced here do not contain a processing-pipeline hash (desc-<hash>) in their names, making the output a clean, shareable BIDS dataset.- Parameters:
path (str |
Path| None) – Directory under which the BIDS dataset will be written. IfNonethe default MNE data directory is used (same default as the rest of MOABB).subjects (list of int | None) – Subject numbers to convert. If
None, all subjects insubject_listare converted.overwrite (bool) – If
True, existing BIDS files for a subject are removed before saving. Default isFalse.format (str) – The file format for the raw EEG data. Supported values are
"EDF"(default),"BrainVision", and"EEGLAB".verbose (str | None) – Verbosity level forwarded to MNE/MNE-BIDS.
generate_figures (bool) – If
True, generate interactive neural signature HTML figures in{bids_root}/derivatives/neural_signatures/. Requiresplotly(pip install moabb[interactive]). Default isFalse.
- Returns:
bids_root – Path to the root of the written BIDS dataset.
- Return type:
Examples
>>> from moabb.datasets import AlexMI
>>> dataset = AlexMI()
>>> bids_root = dataset.convert_to_bids(path="/tmp/bids", subjects=[1])
Notes
Use
CacheConfigto configure caching forget_data(). Usemoabb.datasets.bids_interface.get_bids_rootto get the BIDS root path.Added in version 1.5.
- data_path(subject, path=None, force_update=False, update_path=None, verbose=None)[source]#
Get path to local copy of a subject data.
- Parameters:
subject (int) – Number of subject to use
path (None | str) – Location of where to look for the data storing location. If None, the environment variable or config parameter
MNE_DATASETS_(dataset)_PATHis used. If it doesn’t exist, the “~/mne_data” directory is used. If the dataset is not found under the given path, the data will be automatically downloaded to the specified folder.force_update (bool) – Force update of the dataset even if a local copy exists.
update_path (bool | None Deprecated) – If True, set the MNE_DATASETS_(dataset)_PATH in mne-python config to the given path. If None, the user is prompted.
verbose (bool, str, int, or None) – If not None, override default verbose level (see
mne.verbose()).
- Returns:
path – Local path to the given data file. This path is contained inside a list of length one, for compatibility.
- Return type:
- download(subject_list=None, path=None, force_update=False, update_path=None, accept=False, verbose=None)[source]#
Download all data from the dataset.
This function is only useful to download all the dataset at once.
When the dataset declares a
nemar_idand the download provider is not"upstream", the files come from NEMAR’ssourcedata/– the original pre-BIDS distribution, byte-identical to what the upstream host serves. On any NEMAR failure this falls back to the dataset’s own downloader with a warning (unless the provider is pinned to"nemar"). Seesourcedata_path()andmoabb.set_download_provider().- Parameters:
subject_list (list of int | None) – List of subjects id to download, if None all subjects are downloaded. On the NEMAR path each subject is resolved through the deposit’s
sourcedata_provenance.json; deposits enriched before that manifest recorded subjects fetch the whole tree.path (None | str) – Location of where to look for the data storing location. If None, the environment variable or config parameter
MNE_DATASETS_(dataset)_PATHis used. If it doesn’t exist, the “~/mne_data” directory is used. If the dataset is not found under the given path, the data will be automatically downloaded to the specified folder.force_update (bool) – Force update of the dataset even if a local copy exists.
update_path (bool | None) – If True, set the MNE_DATASETS_(dataset)_PATH in mne-python config to the given path. If None, the user is prompted. Not used on the NEMAR path.
accept (bool) – Accept licence term to download the data, if any. Default: False. Only relevant to the dataset’s own downloader; NEMAR mirrors are already public.
verbose (bool, str, int, or None) – If not None, override default verbose level (see
mne.verbose()).
- get_additional_metadata(subject: str, session: str, run: str)[source]#
Load additional metadata for a specific subject, session, and run.
- Parameters:
- Returns:
A DataFrame containing the additional metadata if available, otherwise None.
- Return type:
None |
pandas.DataFrame
- get_block_repetition(paradigm, subjects, block_list, repetition_list)[source]#
Select data for all provided subjects, blocks and repetitions.
subject -> session -> run -> block -> repetition
See also
- get_data(subjects=None, cache_config=None, process_pipeline=None, n_jobs=1)[source]#
Return the data corresponding to a list of subjects.
The returned data is a dictionary with the following structure:
data = {"subject_id": {"session_id": {"run_id": run}}}
subjects are on top, then we have sessions, then runs. A sessions is a recording done in a single day, without removing the EEG cap. A session is constitued of at least one run. A run is a single contiguous recording. Some dataset break session in multiple runs.
Processing steps can optionally be applied to the data using the
*_pipelinearguments. These pipelines are applied in the following order:raw_pipeline->epochs_pipeline->array_pipeline. If a*_pipelineargument isNone, the step will be skipped. Therefore, thearray_pipelinemay either receive amne.io.Rawor amne.Epochsobject as input depending on whetherepochs_pipelineisNoneor not.- Parameters:
subjects (List of int) – List of subject number
cache_config (dict |
CacheConfig) – Configuration for caching of datasets. SeeCacheConfigfor details.process_pipeline (
sklearn.pipeline.Pipeline| None) – Optional processing pipeline to apply to the data. To generate an adequate pipeline, we recommend usingmoabb.make_process_pipelines(). This pipeline will receivemne.io.BaseRawobjects. The steps names of this pipeline should be elements ofStepType. According to their name, the steps should either return amne.io.BaseRaw, amne.Epochs, or anumpy.ndarray. This pipeline must be “fixed” because it will not be trained, i.e. no call tofitwill be made.n_jobs (int) – Number of jobs to run in parallel over subjects (passed to
joblib.Parallel). Default1(sequential). Per-subject processing (reading, filtering, resampling, epoching) is independent, so this gives a near-linear speedup for datasets with many subjects.
- Returns:
data – dict containing the raw data
- Return type:
Dict
- property metadata[source]#
Return structured metadata for this dataset.
Returns the DatasetMetadata object from the centralized catalog, or None if metadata is not available for this dataset.
- Returns:
The metadata object containing acquisition parameters, participant demographics, experiment details, and documentation. Returns None if no metadata is registered for this dataset.
- Return type:
DatasetMetadata| None
Examples
>>> from moabb.datasets import BNCI2014_001
>>> dataset = BNCI2014_001()
>>> dataset.metadata.participants.n_subjects
9
>>> dataset.metadata.acquisition.sampling_rate
250.0
- sourcedata_path(subject=None, path=None, force_update=False, verbose=None)[source]#
Get the dataset’s original pre-BIDS distribution from NEMAR.
Where
data_path()fetches the original files from the upstream host, this fetches the copy NEMAR mirrors undersourcedata/. The files keep their upstream names, so the two are interchangeable in content – but NEMAR stays reachable when the upstream host is slow, rate-limited, behind a bot gate, or retired.- Parameters:
subject (int | str | None) – Restrict the download to one subject, resolved through the deposit’s
sourcedata_provenance.json. Deposits enriched before that manifest recorded subjects fall back to the whole tree with a warning. WhenNonethe whole tree is fetched.path (None | str) – Base path where MOABB stores datasets.
force_update (bool) – Re-fetch even when a local copy is present.
verbose (bool, str, int, or None) – If not None, override default verbose level.
- Returns:
Local path to the
sourcedatadirectory.- Return type:
- Raises:
ValueError – If the dataset declares no
nemar_id.moabb.datasets.download.NemarDownloadError – If the download fails or the deposit publishes no
sourcedata/.